


This article was automatically translated from the original Turkish version.
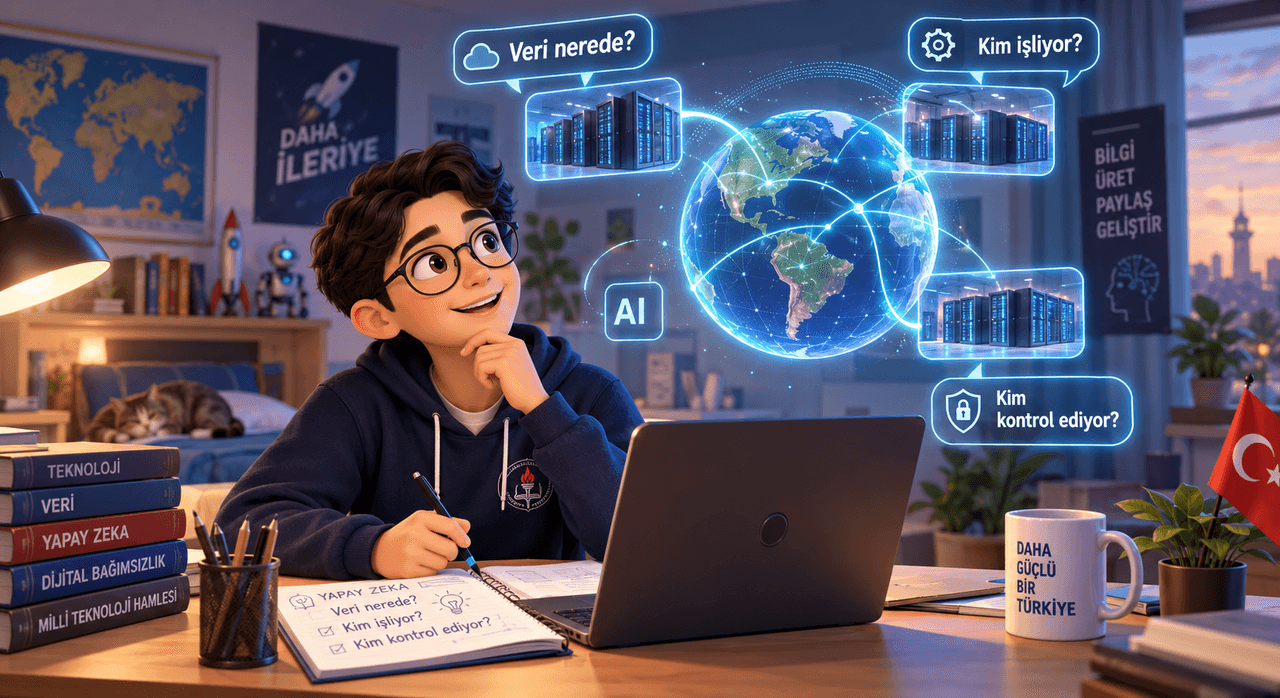
Veri Güvenliği ve Dijital Kontrolü Gösteren Temsili Görsel (Yapay Zekâ ile Oluşturulmuştur.)
Asking questions to artificial intelligence has become an ordinary part of our daily lives. I myself sometimes use AI tools to gather opinions on a topic, summarize a text, or find answers to questions in my mind. We have become so accustomed to receiving answers within seconds after typing just a few words that we often do not think about what is happening in the background.
Yet when I began working on this subject, I realized that what seemed like a simple question brought with it many other questions. Where does my sentence go? Which computer processes this data? In which country is that computer located? Does a system that answers us in Turkish understand only words, or can it also comprehend our idioms and cultural expressions?
Until now, when I heard the word “independence,” I mostly thought of land, sea, and air borders. But as technology has advanced, I have begun to think that independence is not only about physical boundaries. Today, for nations, data has become at least as important as energy, production, and communication infrastructure.
Therefore, while preparing this article, the same question kept recurring in my mind:
Does data have a homeland?
Artificial intelligence often appears to be nothing more than a chat box on a screen. Yet behind that box lie three fundamental interlinked elements: data, computational power, and model.
Data constructs the world that artificial intelligence can learn from. Texts, images, sounds, and numerical measurements become the raw material that enables models to discover patterns. However, possessing the world’s largest data archive alone is not sufficient. To process this data, powerful processors and high-performance computational infrastructure are required.
The model is the point where data and computational power are transformed into usable capability. Systems that generate text, classify images, make predictions, or communicate with humans in natural language emerge at this stage.
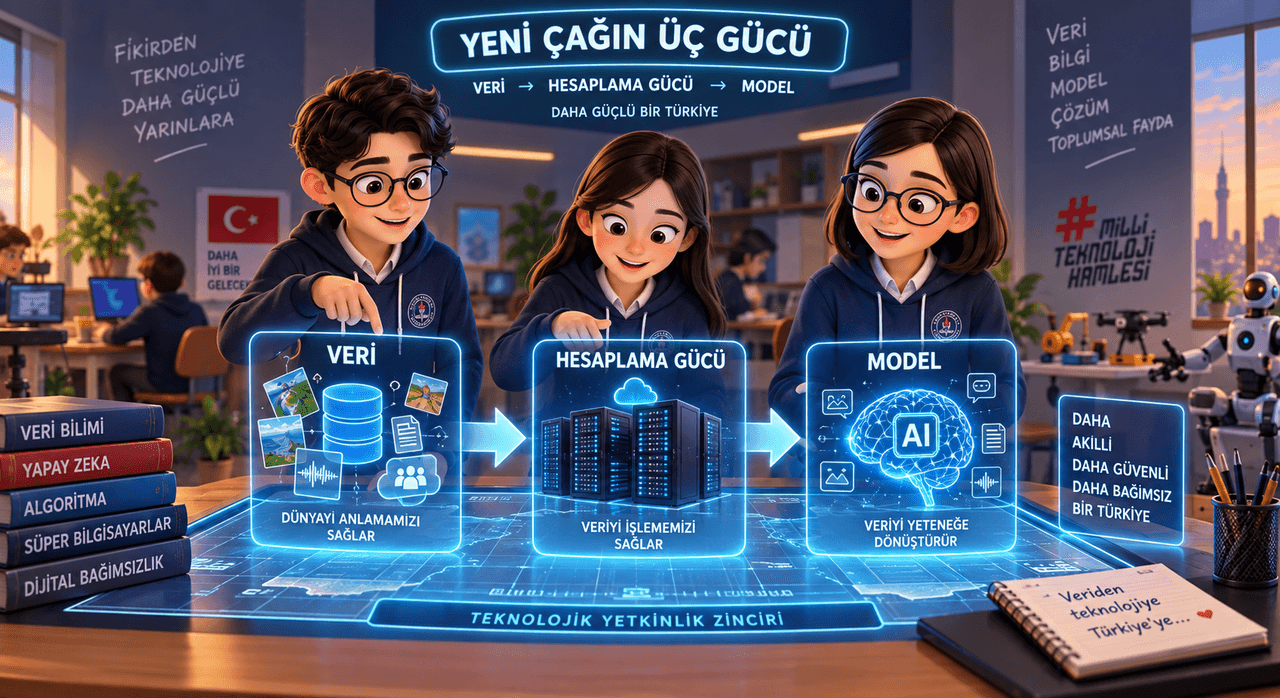
Veri, Hesaplama Gücü ve Yapay Zekâ Modeli İlişkisini Gösteren Temsili Görsel (Yapay Zekâ ile Oluşturulmuştur.)
Thus, one of the fundamental chains of the age of artificial intelligence can be established:
Data → Computational Power → Model → Technological Competence
But the real issue is not merely possessing one link in this chain.
A country may have vast amounts of data; yet if it lacks sufficient computational resources to process that data, it remains dependent on external systems. It may have a strong infrastructure; yet if it cannot develop models tailored to its own language and needs, it must rely on others for much of its technology.
Therefore, digital independence in the age of artificial intelligence carries a broader meaning than simply developing a local application.
The real question is this:
Can we transform our data into knowledge, our knowledge into technology, and our technology into social value?
You may have heard data called “the oil of the new era” in many places. I believe this metaphor is used to convey the value of data; yet to me, data resembles not oil but a memory.
For example, if we collect temperature and humidity data from a field for only one day, we have a few measurements. But if we record the same measurements over years, we no longer have just numbers—we have accumulated knowledge about that field’s history. A similar situation exists with satellite imagery. When we place an image taken years ago side by side with today’s image, we can see how a city has grown, how a forest has changed, or how water resources have been affected.
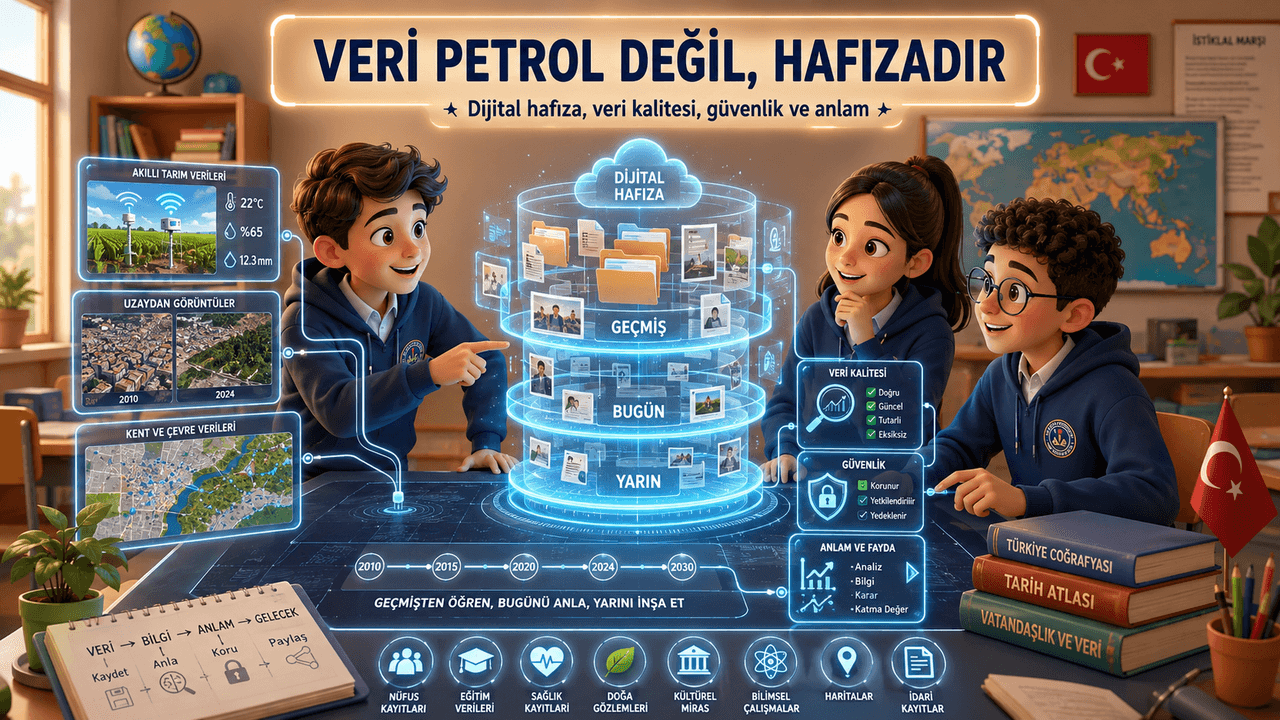
Verinin Dijital Hafızaya Dönüşümünü Gösteren Temsili Görsel (Yapay Zekâ ile Oluşturulmuştur.)
Therefore, the value of data, in my view, is not only about how much there is.
Can we store and interpret that data correctly?
This is the more important question.
This is why in Türkiye’s 2026–2030 Artificial Intelligence Action Plan, it is essential to address data, human resources, digital infrastructure, and AI applications together. The plan outlines goals such as making at least 2,000 public datasets accessible through the National Data Library, training 10,000 advanced AI specialists and 100,000 AI application professionals, and increasing the country’s data center computing capacity to at least one gigawatt by 2030. 【1】
But a society’s digital memory is not composed solely of sensors, measurements, and digital records. One of its most valuable components is stored in a place we use every day:
In our language.
“Etekleri zil çalmak.”
When we hear this idiom, none of us imagines an actual skirt with bells ringing. We immediately understand what is meant. Because we learn Turkish not only from the words taught in school, but from our families, our surroundings, books, films, and everyday conversations.
When I reflect on this point, another key difference between humans and artificial intelligence becomes clear.
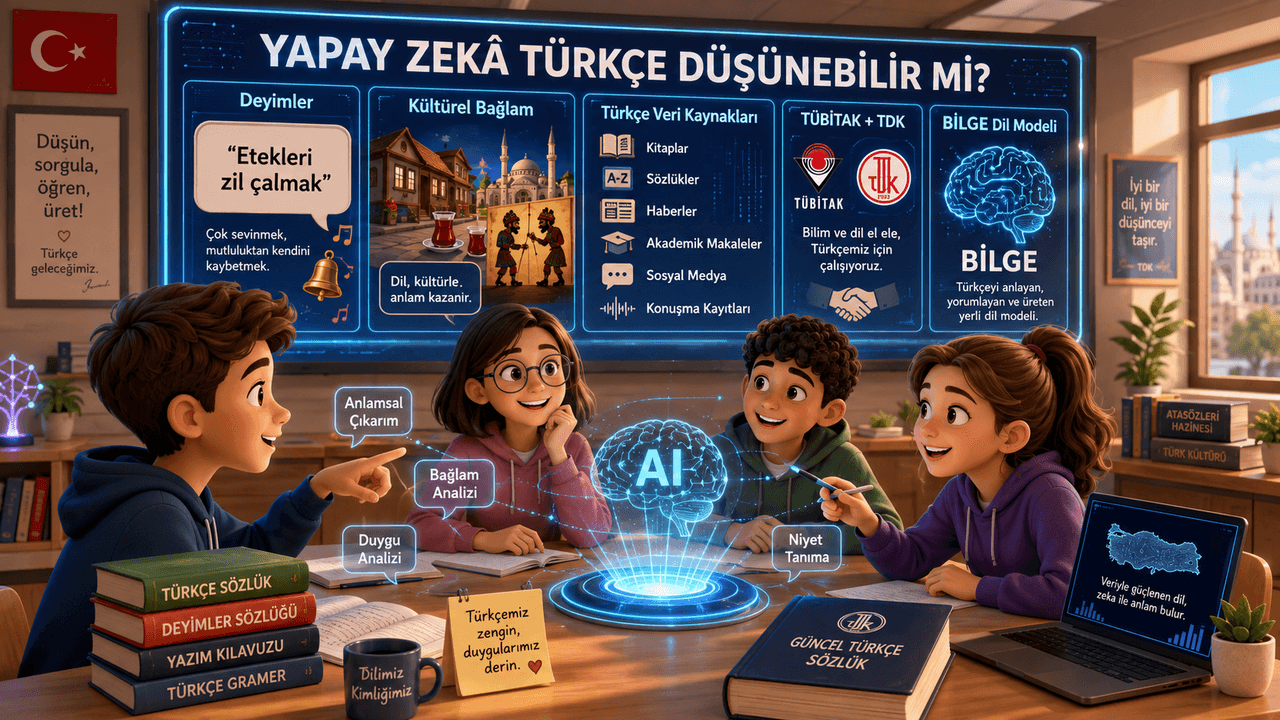
Türkçe, Kültürel Bağlam ve Yapay Zekâ İlişkisini Gösteren Temsili Görsel (Yapay Zekâ ile Oluşturulmuştur.)
An artificial intelligence has no such childhood.
It does not hear an idiom from its grandmother or learn through experience when an proverb should be used. Its relationship with Turkish is built largely through the digital content it encounters.
Therefore, the most interesting question for me is not “Can artificial intelligence think in Turkish?” Rather, I wonder:
How well do we represent Turkish in the digital world?
If in the future we use artificial intelligence systems more widely—from education and science to public services and daily life—it will be crucial for Turkish to be strongly represented in these systems. For this, we need not only large volumes of Turkish text, but accurate, diverse, and high-quality digital content.
Academic studies also draw attention to this need from a Turkish perspective. Acikgoz, Erdogan, and Yuret demonstrate that in languages like Turkish, where digital resources are more limited compared to major languages, data volume, model selection, evaluation methods, and computational capacity significantly affect model performance. 【2】
The 2026 Cetvel study, when evaluating large Turkish language models, does not assess only general language understanding; it also includes Turkish grammar, idiomatic usage, and cultural content in its evaluation scope. 【3】
These studies lead me to think: the ability of an artificial intelligence to construct a few grammatically correct Turkish sentences does not mean it has learned Turkish in all its dimensions. It must also understand the cultural and contextual aspects of the language.
In this context, the collaboration signed in 2024 between TÜBİTAK and the Turkish Language Association (Türk Dil Kurumu) is noteworthy. Under this collaboration, the goal is to digitize TDK’s dictionaries, encyclopedias, and grammar books and use these resources in Turkish Large Language Model development. 【4】
Thus, an invisible bridge is being built between the linguistic heritage of the past and the technology of the future:
From dictionary to dataset, from word to model, from cultural memory to digital future…
One of Türkiye’s current initiatives in this field is the BİLGE Language Model. According to a statement from the Ministry of Industry and Technology dated 29 July 2026, BİLGE, developed by TÜBİTAK, is a model with 37 billion parameters and is planned to be made available to developers. The ministry’s statement links the representation of Turkish and societal memory in AI models with technological independence. 【5】
While researching BİLGE, the first detail that caught my attention was its 37 billion parameters. At first glance, such large numbers seem impressive. But after further reflection, I realized that this number is not the most important point.
Because to develop a model, you first need to prepare the data. Then you need powerful computers to run it, researchers to train it, and people to test and refine the results.
Therefore, seeing BİLGE merely as “a language model developed by Türkiye” feels incomplete to me. I believe the more important aspect is its contribution to building the knowledge and expertise within Türkiye needed to develop such a model.
After all, the issue is not only about machines learning Turkish.
We also need the knowledge to transfer our own language into the technologies of the future.
An artificial intelligence model can generate a few lines of text on screen. Yet behind those few lines lies a very physical world.
Developing large models requires enormous computational power. Therefore, high-performance computing systems have become one of the fundamental tools of modern AI research.
One of the key examples of this infrastructure in Türkiye is TRUBA – the Turkish National Science Infrastructure, operated by TÜBİTAK ULAKBİM. The ARF-ACC system within TRUBA has powerful GPU resources suitable for AI and data-intensive applications. According to TÜBİTAK ULAKBİM, 192 NVIDIA H200 GPUs were added to the system in 2025 to increase its computational capacity. 【6】
As of the June 2026 edition of the TOP500 list, which ranks the world’s most powerful supercomputers, ARF-ACC stands at 165th place. 【7】
But the important point here is not the ranking number itself. More valuable is the existence of infrastructure within Türkiye that allows researchers to access high-performance computing for advanced work.
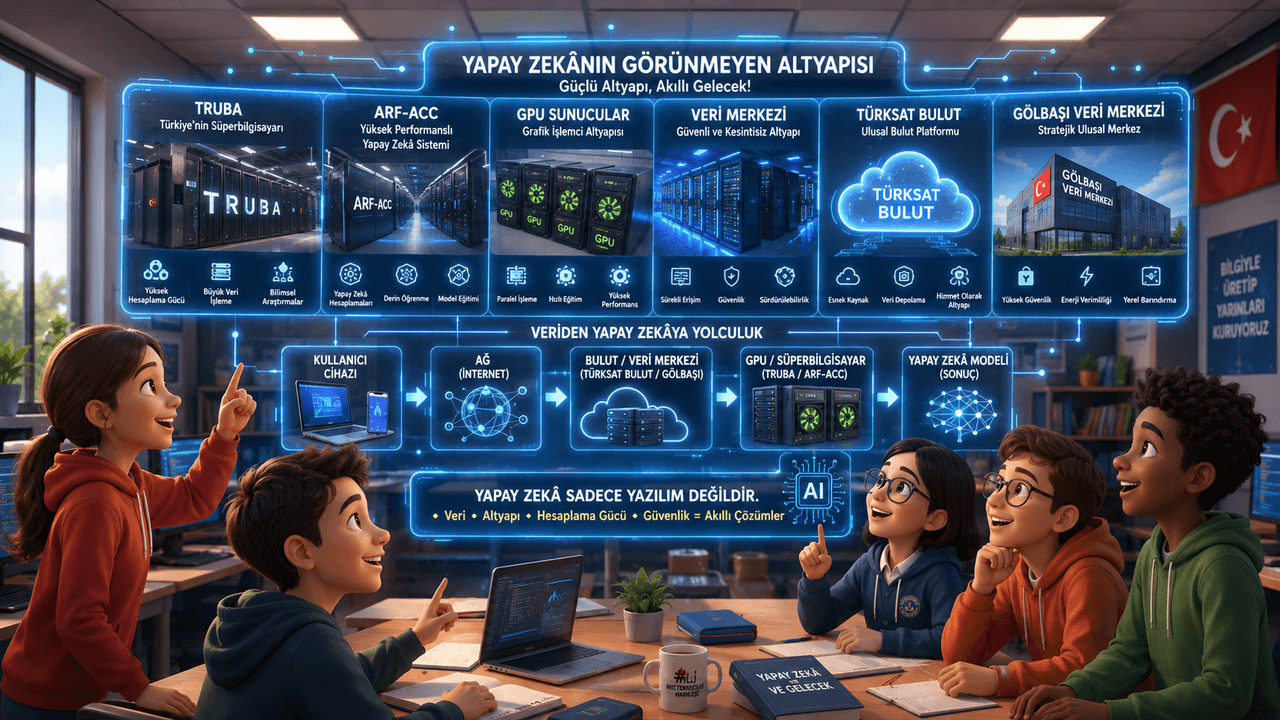
Yapay Zekânın Hesaplama ve Veri Merkezi Altyapısını Gösteren Temsili Görsel (Yapay Zekâ ile Oluşturulmuştur.)
An AI idea can emerge in Türkiye, its data can be prepared here, and its algorithm can be developed here. Yet if access to the necessary computational power for training the model is lacking, one of the critical links in the chain is missing.
Therefore, supercomputers are not merely very fast computers.
They are the digital laboratories of modern science.
So where do all these data and computing systems operate?
In everyday language, we say we upload our photos “to the cloud.” Yet the cloud is not in the sky at all. Data is stored on physical servers; processors consume energy; network systems transmit data; and the resulting heat is controlled by cooling infrastructure.
Thus, behind the digital world lies a highly concrete structure:
Data centers.
One of Türkiye’s current examples is the Türksat Cloud platform. Türksat announced on 27 February 2026 that its new system aims to ensure that public and private sector data are stored within a domestic ecosystem, strengthen strategic data security, and support AI-driven digital transformation. 【8】
One physical dimension of this approach is the Türksat Gölbaşı Data Center, currently under construction in Ankara. The center, whose foundation was laid on 22 July 2026, is planned to consolidate a significant portion of public institutions’ information and cloud infrastructure under one roof and provide the necessary infrastructure for digital services requiring high processing capacity. 【9】
All of this reminds us of a simple but vital truth:
The digital world has its own concrete, electricity, cabling, and cooling systems.
No matter how abstract data, models, and algorithms may seem, artificial intelligence is not independent of physical infrastructure. Digital competence is not only about developing good software; it is also about having access to the infrastructure on which that software runs.
So far, we have discussed different technologies such as data, language models, supercomputers, and data centers. Yet none of these alone means digital independence.
I believe we must define the term “independence” correctly here.
Digital independence does not mean that Türkiye must produce all its processors, software, and technologies on its own. Today’s technology rises on a global ecosystem of knowledge and production. Open-source projects, international scientific collaborations, and global supply chains are essential components of modern technology.
The real issue is not disconnection from the world, but the capacity with which we connect to it.
Academic studies on digital sovereignty also do not evaluate the issue solely through physical borders or where technology is manufactured. Huw Roberts links digital sovereignty to the question of who holds control and decision-making authority over digital technologies. 【10】
From this perspective, digital independence is less about producing every technology independently and more about possessing the knowledge, infrastructure, and alternative development capacity to have a voice in critical technologies.
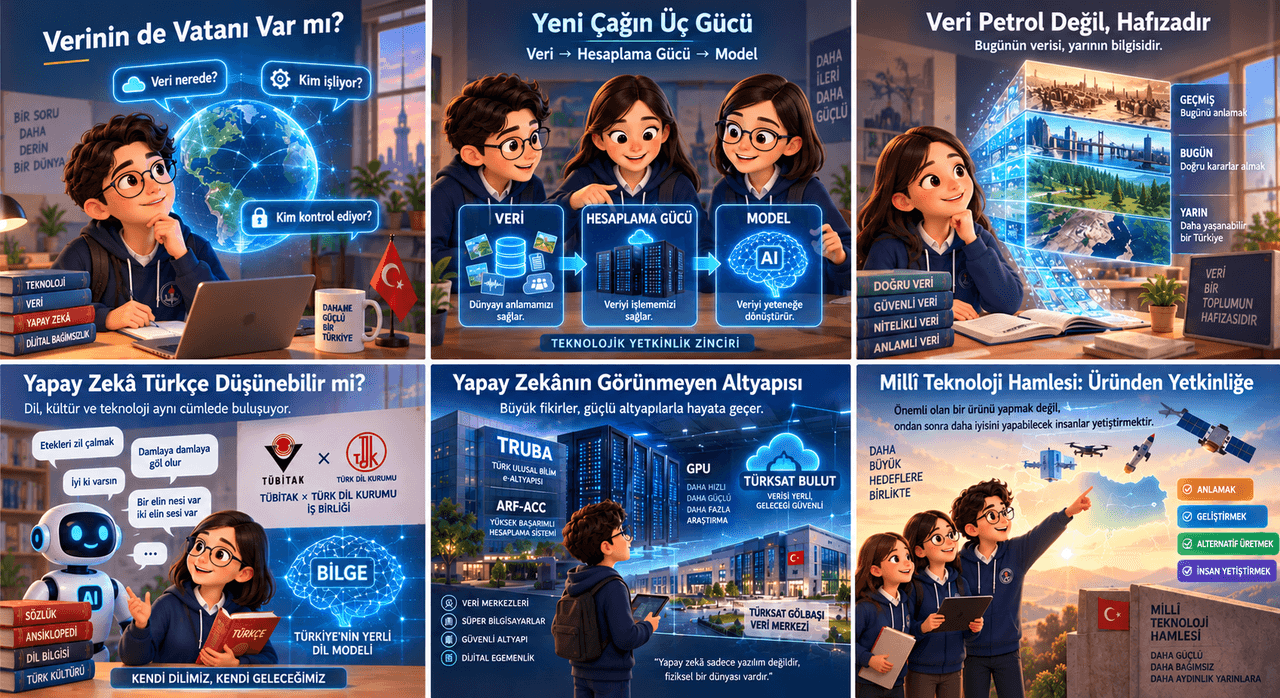
Teknolojik Yetkinlik ve İnsan Kaynağı İlişkisini Gösteren Temsili Görsel (Yapay Zekâ ile Oluşturulmuştur.)
Because dependency is sometimes not about purchasing a product from abroad, but not knowing what to replace it with when it is gone.
If a country has the human resources capable of understanding the technologies it uses, evaluating their security, adapting them to its needs, and developing alternatives when necessary, its room for maneuver expands.
Therefore:
The measure of digital independence is not the height of walls, but the breadth of options.
Evaluating the National Technology Initiative solely by the products it produces is inadequate. A satellite, an AI model, or a supercomputer is certainly important; but there is a more important question:
Will we be able to build the next one after this?
Because technology changes rapidly. Today’s advanced model may become outdated in a few years. Today’s powerful computer may fall behind in rankings over time. Software architectures, processors, and data center technologies are constantly evolving.
What endures is not individual products, but the ability to produce.
While researching this topic, it was easy to speak of data centers, supercomputers, and models with billions of parameters. All have measurable numerical properties. But I believe the most important component behind all these systems is not a number:
People.
After all, it is people who develop AI models, build data centers, and test new algorithms.
I also believe students are not outside this chain. What a student does when writing their first lines of code in school may seem simple. But if they continue engaging with technology, in a few years they may develop larger projects, conduct research at university, or find new solutions to problems never before imagined.
I believe one of the most important aspects of the National Technology Initiative lies here.
Not only producing technology, but cultivating people who can produce technology.
Because when a product becomes obsolete, it is again people who will develop its successor.
When I started this article, I viewed the question “Does data have a homeland?” as merely a provocative title. As I researched, I realized this question has no single-word answer.
Data has no passport. It does not stand at border checkpoints. It reaches other countries in seconds over the internet. The same data can be generated in one place, stored elsewhere, and processed by computers in yet another country.
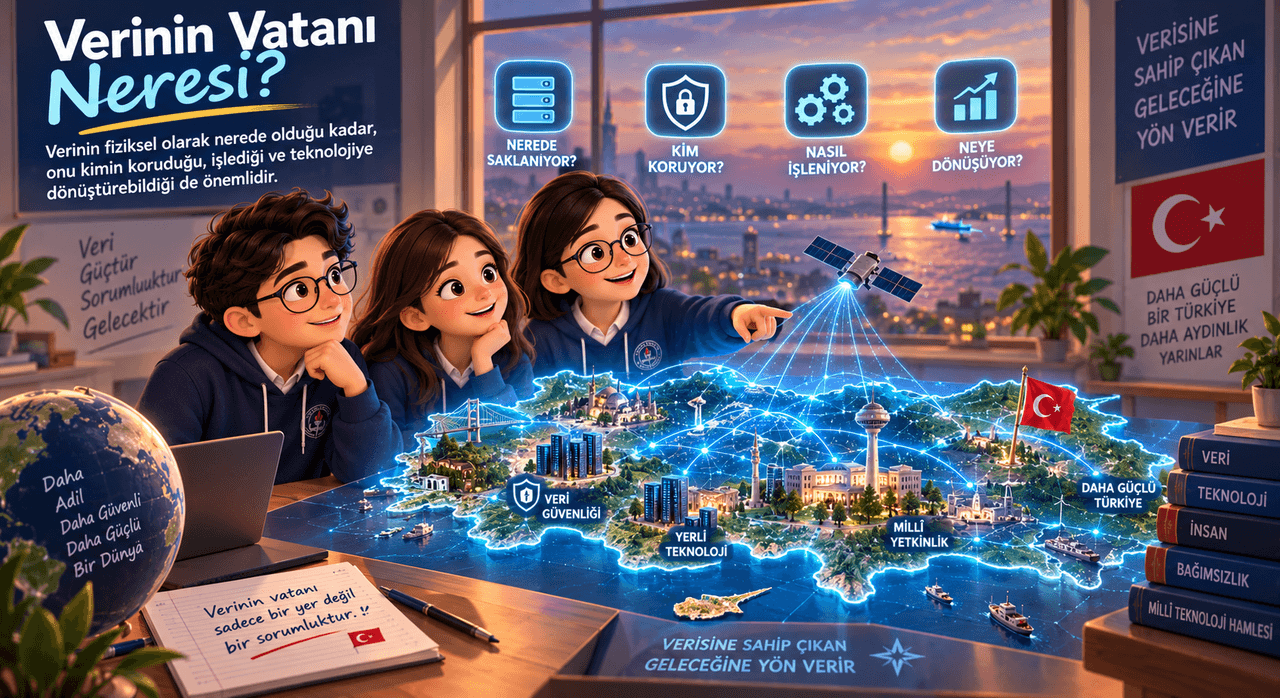
Verinin Korunması, İşlenmesi ve Teknolojiye Dönüştürülmesini Gösteren Temsili Görsel (Yapay Zekâ ile Oluşturulmuştur.)
Therefore, for me, the real issue is no longer merely where data is located.
What we can do with that data.
Can we securely store our own data? Do we have the infrastructure to process it? Can we extract new knowledge from it and develop our own technologies?
Behind a simple question we ask an AI in seconds lies a vast system—from data centers and processors to language models and researchers. Therefore, I believe artificial intelligence is not merely an application; it is an ecosystem where many different technologies and people come together.
The National Technology Initiative should therefore be evaluated not only by the products it produces, but by its capacity to create future products.
Perhaps data truly has no homeland.
But if a society can protect its own data, understand it, and use it to produce new technologies, it can have greater control over its own digital future.
I believe independence in the age of artificial intelligence begins here.
Acikgoz, Emre Can, Mete Erdogan, and Deniz Yuret. “Bridging the Bosphorus: Advancing Turkish Large Language Models through Strategies for Low-Resource Language Adaptation and Benchmarking.” *Proceedings of the Fourth Workshop on Multilingual Representation Learning (MRL 2024).* (2024): 242–268. Accessed September 9, 2026.https://aclanthology.org/2024.mrl-1.21.pdf
Er, Yakup Abrek, Ilker Kesen, Gözde Gül Şahin, and Aykut Erdem. “Cetvel: A Unified Benchmark for Evaluating Language Understanding, Generation and Cultural Capacity of LLMs for Turkish.” *Proceedings of the 19th Conference of the European Chapter of the Association for Computational Linguistics (Volume 1: Long Papers).* (2026): 1052–1085. Accessed September 9, 2026.https://aclanthology.org/2026.eacl-long.46.pdf
Roberts, Huw. “Digital Sovereignty and Artificial Intelligence: A Normative Approach.” *Ethics and Information Technology* 26 (2024): Article 70. Accessed September 9, 2026.https://link.springer.com/content/pdf/10.1007/s10676-024-09810-5.pdf
T.C. Ministry of Industry and Technology. "Turkey’s Native Language Model ‘BİLGE’ Is Opened to Developers’ Use." T.C. Ministry of Industry and Technology. Accessed September 9, 2026.https://www.sanayi.gov.tr/medya/haber/turkiyenin-yerli-dil-modeli-bilge-gelistiricilerin-kullanimina-aciliyor
T.C. Ministry of Industry and Technology. "Türkiye Yapay Zekâ Eylem Planı Açıklandı." T.C. Ministry of Industry and Technology. Accessed September 9, 2026.https://www.sanayi.gov.tr/medya/haber/turkiye-yapay-zek%C3%A2-eylem-plani-aciklandi
TOP500. "ARF ACC – ThinkSystem SD650-N V3." Accessed September 9, 2026.https://www.top500.org/system/180350/
TÜBİTAK ULAKBİM. "ARF-ACC Süper Bilgisayarlarımızdan Performans Artışı!" Accessed September 9, 2026.https://ulakbim.tubitak.gov.tr/arf-acc-super-bilgisayarlarimizdan-performans-artisi/
Türkiye Bilimsel and Technological Research Institution (TÜBİTAK). "TÜBİTAK ve TDK Dijitalde Güçlerini Birleştiriyor." TÜBİTAK. Accessed September 9, 2026.https://tubitak.gov.tr/tr/haber/tubitak-ve-tdk-dijitalde-guclerini-birlestiriyor
Türksat Uydu Haberleşme Kablo TV ve İşletme A.Ş. "Türksat Bulut ile Türkiye'nin Verisi Yerli Altyapıda Yükselecek." TÜRKSAT. Accessed September 9, 2026.https://www.turksat.com.tr/kurumsal/basin-medya/haberler/turksat-bulut-ile-turkiyenin-verisi-yerli-altyapida-yukselecek
Türksat Uydu Haberleşme Kablo TV ve İşletme A.Ş. "Türksat Gölbaşı Veri Merkezi'nin Temeli Atıldı." *TÜRKSAT.* Accessed September 9, 2026.https://www.turksat.com.tr/kurumsal/basin-medya/haberler/turksat-golbasi-veri-merkezinin-temeli-atildi
[1]
T.C. Sanayi ve Teknoloji Bakanlığı, “Türkiye Yapay Zekâ Eylem Planı Açıklandı,” T.C. Sanayi ve Teknoloji Bakanlığı, erişim 9 Eylül 2026, https://www.sanayi.gov.tr/medya/haber/turkiye-yapay-zek%C3%A2-eylem-plani-aciklandi
[2]
Emre Can Acikgoz, Mete Erdogan ve Deniz Yuret, “Bridging the Bosphorus: Advancing Turkish Large Language Models through Strategies for Low-Resource Language Adaptation and Benchmarking,” Proceedings of the Fourth Workshop on Multilingual Representation Learning (MRL 2024) (2024), s. 242, erişim 9 Eylül 2026, https://aclanthology.org/2024.mrl-1.21.pdf
[3]
Yakup Abrek Er, Ilker Kesen, Gözde Gül Şahin ve Aykut Erdem, “Cetvel: A Unified Benchmark for Evaluating Language Understanding, Generation and Cultural Capacity of LLMs for Turkish,” Proceedings of the 19th Conference of the European Chapter of the Association for Computational Linguistics (Volume 1: Long Papers) (2026), s. 1052, erişim 9 Eylül 2026, https://aclanthology.org/2026.eacl-long.46.pdf
[4]
Türkiye Bilimsel ve Teknolojik Araştırma Kurumu (TÜBİTAK), “TÜBİTAK ve TDK Dijitalde Güçlerini Birleştiriyor,” TÜBİTAK, erişim 9 Eylül 2026, https://tubitak.gov.tr/tr/haber/tubitak-ve-tdk-dijitalde-guclerini-birlestiriyor
[5]
T.C. Ministry of Industry and Technology. "Turkey’s Native Language Model 'BİLGE' Is Opened to Developers' Use." Accessed September 9, 2026.
[6]
TÜBİTAK ULAKBİM, “ARF-ACC Süper Bilgisayarlarımızdan Performans Artışı!,” TÜBİTAK ULAKBİM, erişim 9 Eylül 2026, https://ulakbim.tubitak.gov.tr/arf-acc-super-bilgisayarlarimizdan-performans-artisi/
[7]
TOP500, “ARF ACC – ThinkSystem SD650-N V3,” TOP500, erişim 9 Eylül 2026, https://www.top500.org/system/180350/
[8]
Türksat Uydu Haberleşme Kablo TV ve İşletme A.Ş. "Türksat Bulut ile Türkiye'nin Verisi Yerli Altyapıda Yükselecek." TÜRKSAT, Accessed September 9, 2026.https://www.turksat.com.tr/kurumsal/basin-medya/haberler/turksat-bulut-ile-turkiyenin-verisi-yerli-altyapida-yukselecek
[9]
Türksat Uydu Haberleşme Kablo TV ve İşletme A.Ş. "Türksat Gölbaşı Veri Merkezi'nin Temeli Atıldı." *TÜRKSAT*, Accessed September 9, 2026.https://www.turksat.com.tr/kurumsal/basin-medya/haberler/turksat-golbasi-veri-merkezinin-temeli-atildi
[10]
Huw Roberts, “Digital Sovereignty and Artificial Intelligence: A Normative Approach,” Ethics and Information Technology 26, no. 70 (2024), s. 1, erişim 9 Eylül 2026, https://link.springer.com/content/pdf/10.1007/s10676-024-09810-5.pdf
The Three Powers of the New Era
Data Is Not Oil, It Is Memory
Can Artificial Intelligence Think in Turkish?
The Invisible Infrastructure of Artificial Intelligence
National Technology Initiative: From Product to Competence
Where Is the Homeland of Data?